MCP servers, plainly explained
What an MCP server actually does, what the 2026-07-28 spec changed, and how AWS Knowledge MCP differs from AWS Documentation MCP.
Viktor Vedmich · 13 min read
Ask a coding assistant which fields a VPC flow log record contains, and it answers from its training data: fluent, confident and possibly out of date. An MCP server is how you give it a better source.
An MCP server is a small program that gives an AI application one new capability: search these docs, query that database, run this CLI. The Model Context Protocol (MCP), which Anthropic introduced in November 2024, is the contract that makes those programs pluggable.
Before MCP, every AI application wired up integrations its own way. A tool that let one assistant query your PostgreSQL database had to be rebuilt for the next IDE. MCP’s own documentation compares the protocol to a USB-C port for AI applications: one connector, many devices. Like USB-C, it only works when both ends agree on the details. We will come back to that at the end.
The shape of it
Three roles. The host is the application you work in: Claude Code, an IDE, an agent framework. Inside the host, an MCP client holds the connection to exactly one MCP server. A host with five servers runs five clients.
Most servers are about tools, and the flow goes like this:
- The client asks the server what it offers (
tools/list). Each tool comes back with a name, a description and a JSON Schema for its input. - The host hands those definitions to the model along with your prompt.
- When the model wants a tool, it proposes a call. The host checks it, asks you if needed, and the client sends
tools/call. - The server runs the tool and returns a result. The host puts the result back into the model’s context.
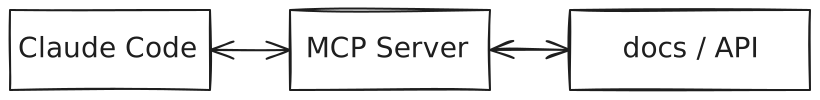
The host orchestrates, the server integrates, the model decides. Note what the model does not do: it never talks to the server. It proposes a call, and the host makes it.
Tools are one of three things a server can offer. Resources are data the application can read, each identified by a URI. Prompts are message templates the user can pick. All of it travels as JSON-RPC 2.0 messages.
What the current spec says
The latest revision as of October 2026 is 2026-07-28. Four things about it are worth getting right:
- Two standard transports. With stdio, the client launches the server as a subprocess, and the two exchange newline-delimited JSON-RPC over
stdinandstdout. With Streamable HTTP, every message is an HTTP POST to one MCP endpoint, and the reply comes back as JSON or as an SSE stream scoped to that request. Anything else, WebSocket included, is a custom transport. The spec allows custom transports, but they only work when both sides implement them. Claude Code, for example, accepts awsserver type in its JSON config. That is a client feature, not part of the standard. - No protocol sessions. There is no
initializehandshake anymore. Every request carries its protocol version and client capabilities in_meta, so MCP itself no longer needs session affinity. Whether any instance can serve a call still depends on where the tool keeps its own state. A server that needs state across calls (an open transaction, a shopping cart) returns an explicit handle from one tool and takes it as an argument in the next. - The client starts every exchange. Servers must not send JSON-RPC requests. They answer requests, may send notifications about a request in flight (progress, for example), and send change notifications on a stream the client opened with
subscriptions/listen. When a server needs something mid-call, such as a confirmation from the user, it replies with aninput_requiredresult, and the client retries the original request with the answers attached. - A subscription tells you that something changed, not what. For a subscribed resource, the server sends
notifications/resources/updatedwith the URI. The client then fetches the new content withresources/read.
The third point is the one that surprises people. Under the current spec, a server cannot send the client a single request. Everything it says is either an answer or a notification.
Update, October 2026: The first version of this post called MCP bidirectional, stateful and transport-agnostic, said servers could push resources to the client, and listed WebSocket as a transport. The 2025-11-25 revision did have an
initializehandshake, sessions and server-initiated requests, but even there a subscription only signalled that a resource had changed, and WebSocket was never a standard transport. The 2026-07-28 revision removed the handshake and protocol sessions, replaced server-initiated requests with multi round-trip requests and moved change notifications tosubscriptions/listen. It also deprecated Roots, Sampling and Logging. Clients and servers that support both eras detect the other side and fall back.
Three servers I use
Two of the three are AWS servers, and yes, I work at AWS. Here is what each one does and where it runs.
AWS Documentation MCP is a local server. The client starts it with uvx and talks to it over stdio. Its tools search the AWS documentation through the official AWS documentation search API (search_documentation), fetch a page as Markdown (read_documentation, read_sections), pull matching rows out of large tables such as service quotas (search_table) and suggest related pages (recommend). I ask: “Which fields does a VPC flow log record contain? Cite the page.” The model searches, reads the page and answers from the current documentation, with a link I can check.
AWS Knowledge MCP is a fully managed remote server that AWS hosts at https://knowledge-mcp.global.api.aws, reachable over Streamable HTTP. It needs no AWS account and no authentication. It is rate-limited, though, and your client has to support remote servers (or run a stdio-to-HTTP proxy). It indexes more than the documentation: API references, What’s New posts, Getting Started material, blog posts, architectural references, Well-Architected guidance, troubleshooting guides, CDK and CloudFormation docs, Amplify and Strands Agents docs, and agent skills. It also answers regional availability questions. I reach for it when the answer spans several sources: “Is this API available in my Region, and what does Well-Architected say about the pattern?”
The difference in one table:
| AWS Documentation MCP | AWS Knowledge MCP | |
|---|---|---|
| Where it runs | Local process, started by the client | Remote, managed by AWS |
| Transport | stdio | Streamable HTTP |
| AWS credentials | None in its configuration | None, no AWS account needed |
| Sources | AWS documentation | Documentation plus all the sources listed above |
| Extras | Table search, page recommendations | Regional availability, agent skills |
If your client supports remote servers, Knowledge MCP covers more ground, and its own FAQ suggests simply trying it. Documentation MCP still earns its place when you want a local process or need the AWS China documentation. With AWS_DOCUMENTATION_PARTITION=aws-cn it exposes only read_documentation and get_available_services.
QMD searches my Obsidian vault. QMD (“Query Markup Documents”) is an open-source local search engine for Markdown. It offers BM25 full-text search (qmd search), vector search (qmd vsearch) and a hybrid mode with query expansion, reciprocal rank fusion and LLM reranking (qmd query), with the models running on your machine. qmd mcp exposes the same search as an MCP server, over stdio by default, or over HTTP when you want one shared long-lived process. My vault holds architecture notes, Kubernetes troubleshooting write-ups and course material. I ask “Show me my notes on Karpenter consolidation”, the model calls QMD’s query tool, gets the matching notes with their paths and answers from my own notes instead of generic training data.
Here are all three in a Claude Code project .mcp.json: two local processes and one remote endpoint.
{
  "mcpServers": {
    "awslabs.aws-documentation-mcp-server": {
      "command": "uvx",
      "args": ["awslabs.aws-documentation-mcp-server@latest"],
      "env": {
        "FASTMCP_LOG_LEVEL": "ERROR",
        "AWS_DOCUMENTATION_PARTITION": "aws"
      }
    },
    "aws-knowledge-mcp-server": {
      "type": "http",
      "url": "https://knowledge-mcp.global.api.aws"
    },
    "qmd": {
      "command": "qmd",
      "args": ["mcp"]
    }
  }
}
Each of these is a thin layer over a data source. The model does the reasoning, the server does the access. And all three only read. Plenty of servers also write: they open tickets, apply Kubernetes manifests, change cloud resources. Same protocol, very different blast radius.
What “plainly” means here
MCP servers are not magic. A server is a JSON-RPC API with a schema contract.
If the source is wrong, the answer is wrong. Outdated documentation gives outdated answers, and a database with bad data feeds the model bad data. The model treats tool output as evidence, so you decide which servers deserve that trust. Anything a server fetches from the outside world is untrusted input: fetched content is a classic path for prompt injection.
Authentication depends on the server. AWS Knowledge MCP needs none. AWS Documentation MCP takes no AWS credentials in its configuration. Servers that call AWS APIs use whatever credentials you give them, usually an AWS profile and a Region. For HTTP servers, the spec defines an OAuth-based authorization flow. For stdio, it says to take credentials from the environment instead.
With stdio, the client launches the server as a local process. That process runs with your OS user’s permissions and with whatever credentials and environment variables it receives. A server started with an admin profile can do anything that profile allows, whether or not you meant to hand that over. So give each server the narrowest credentials that still do the job, and prefer servers that are read-only by default. The EKS MCP server, for example, refuses mutating operations until you add --allow-write. Keep a human approving the calls that change things: the spec says there should always be someone who can deny a tool call.
Context is a budget. Every tool definition in the model’s context costs tokens, and clients that send all definitions upfront spend that budget before your first prompt. The cost depends on the number of tools, the size of their schemas and how the client loads them, not on the number of servers alone. Clients deal with this differently. Claude Code defers MCP tools by default: only tool names and server instructions load at session start, and full definitions come in through tool search when needed. Kiro’s powers, introduced in December 2025, bundle MCP server configuration with instructions and activate on keywords in the conversation, so a power’s tools load only when the task calls for them. The cheapest fix works in every client: connect only the servers the work needs.
When to write your own
Start with servers that someone maintains. On 5 October 2026, the awslabs/mcp repository had 61 server directories under src/, one of them marked deprecated, for services such as EKS, ECS, CloudWatch, DynamoDB, IAM, pricing and billing.
Be careful with the old reference servers. The original PostgreSQL, GitHub, Slack and Google Drive servers from the MCP project are archived in servers-archived, with no maintenance and no security updates. The active reference set (Filesystem, Git, Fetch, Memory and a few others) exists to demonstrate the protocol and the SDKs, and its README says these servers are not production-ready. For a real integration, pick an actively maintained server, often the vendor’s own, and look it up in the MCP Registry. For a sense of scale: in December 2025, the MCP project counted 10,000 active servers.
Write your own when nothing fits your domain. Your internal API, your CMDB, your ticketing system, your deployment pipeline: first check whether an existing connector or an OpenAPI-based server fits, and write your own when it doesn’t. The protocol is the easy part, because the official SDKs handle the wire (Tier 1 SDKs exist for TypeScript, Python, Go, C#, Rust and Ruby). The hard part is making the tools useful. A tool that dumps a whole table as JSON is worse than no tool at all. Return useful slices: filtered, paginated, with the fields the model needs for its next step.
Check what exists before you build. My vault looked like a job for a custom server. It has its own folder structure, and the generic Filesystem server finds files by glob pattern, not notes by meaning. QMD already did the hard part, hybrid search with reranking over Markdown, and its MCP mode was all I needed.
Where this is going
MCP’s next stop after the IDE is production agents. Amazon Bedrock AgentCore Runtime can host MCP servers over Streamable HTTP, and AgentCore Gateway turns APIs and Lambda functions into MCP-compatible tools behind one endpoint. Strands Agents loads an MCP server’s tools and hands them to the agent like any other tool. The server you use in Claude Code can sit behind a production agent. The stateless core of the 2026-07-28 spec helps here: without protocol sessions, requests spread across instances like any other HTTP workload, as long as the tool itself doesn’t pin state to one replica.
That shift from dev tool to production runtime changes what matters. Latency, reliability and observability start to count. A server that is fine for interactive IDE use can be too slow or too brittle for an agent loop that calls tools in parallel and retries failures.
If you build servers for production agents, treat them like any other service. Log every tool call. Export call count, latency and error rate. Report tool failures as tool execution errors (isError: true) with an actionable message, so the agent can fix its input and retry instead of guessing. Return machine-readable data in structuredContent, with an outputSchema where it helps. Retry transient failures with bounded exponential backoff, and make sure a repeated call can’t duplicate a write. And load-test against explicit latency, concurrency and throughput targets before an agent depends on the server.
The contract
MCP is an open standard. In December 2025, Anthropic donated it to the Agentic AI Foundation (AAIF), a directed fund under the Linux Foundation. The foundation is co-founded by Anthropic, Block and OpenAI, with support from Google, Microsoft, AWS, Cloudflare and Bloomberg. The spec and the SDKs are open source, and the MCP maintainers keep the technical direction.
That is the point. You build a server once, and it works in Claude Code, Cursor, Kiro, VS Code and other clients. The condition: both sides share a protocol version and a transport, and the client supports the features the server relies on. The 2026-07-28 revision changed what goes over the wire, so check those three before you promise “works everywhere”.
If you have ever built the same integration for five different AI tools, you know why that matters.
Related
- Talk: Building Production GenAI: MCP and Multi-Agent Systems in Action, Code Europe, Krakow, 2025-07-01. MCP shown through Kubernetes troubleshooting and Terraform generation demos.
- Chalk talk: AWS Summit Warsaw 2026 (DOP202), Integrated AI Agents & Code Assistants with MCP & AWS, 2026-05-06.
- Specification: modelcontextprotocol.io/specification/latest (external, canonical).
Sources
Protocol and AWS statements checked against these official sources on 2026-10-05.
- MCP specification 2026-07-28: transports, message patterns, resources, tools and key changes since 2025-11-25
- MCP blog: The 2026-07-28 Specification and MCP joins the Agentic AI Foundation
- modelcontextprotocol/servers and modelcontextprotocol/servers-archived
- awslabs/mcp: AWS Knowledge MCP Server, AWS Documentation MCP Server and Amazon EKS MCP Server
- AWS Knowledge MCP Server general availability (What’s New, 2025-10-01)
- Deploy MCP servers in AgentCore Runtime and AgentCore Gateway
- Strands Agents: MCP tools
- Claude Code: MCP and Introducing Kiro powers
- tobi/qmd